REST and GraphQL are the two API styles most product teams weigh when they design a new backend. REST exposes many resource URLs and leans on plain HTTP. GraphQL exposes one endpoint and a typed schema, and lets each client ask for exactly the data it needs. Both are mature, both run large production systems, and both can be the wrong choice for a given project.
Most articles on REST vs GraphQL are written by vendors that sell one side, or they stop at “GraphQL avoids over-fetching”. In practice the decision turns on less glamorous questions: who consumes the API, how much caching you need, and whether your team can run the extra controls GraphQL requires in production. These are the questions we work through before any web application development project with a non-trivial backend.
This guide covers the basics, then goes further than the usual comparison: the operating cost of GraphQL, the hybrid gateway pattern, migration paths in both directions, what changed in the 2025 specifications, how AI agents consume each style, and a relative cost table. If you are planning a dedicated integration layer, our API development team applies the same framework.
TL;DR: REST or GraphQL?
Choose REST for public and partner APIs, resource-shaped CRUD, heavy HTTP and CDN caching, and simple operations. Choose GraphQL when several clients — web, iOS, Android — need differently shaped, nested data from many sources, and your team can run schema governance and query-cost controls. Many mature products use both, each for a different audience.
- REST’s strengths: plain HTTP semantics, cache-friendly GET requests, simple per-endpoint security and a contract format (OpenAPI) every tool understands.
- GraphQL’s strengths: one typed schema, client-shaped responses, fewer round-trips for nested screens and additive evolution without URL versions.
- GraphQL’s hidden cost: caching, query-cost limits, N+1 batching and per-resolver monitoring are extra work you must plan and budget.
- Both specs moved in 2025: OpenAPI 3.2.0 shipped in September 2025, and so did the first new GraphQL specification edition since 2021.
What is a REST API?
A REST API is an HTTP interface that exposes your data as resources, each with its own URL, and uses standard HTTP methods to read and change them. REST is not a protocol or a library. It is an architectural style that Roy Fielding described in his 2000 doctoral dissertation, defined by a set of constraints: client–server separation, stateless requests, cacheable responses, a uniform interface, a layered system and, optionally, code on demand.
In day-to-day engineering, “REST” means a few concrete habits. Resources are nouns in the URL (/users/42, /users/42/orders). Methods carry the intent: GET reads, POST creates, PUT or PATCH updates, DELETE removes. Status codes report the outcome (200, 201, 404, 409), and headers such as Cache-Control and ETag control caching. All of this rests on the HTTP semantics standardised in RFC 9110 and the caching rules in RFC 9111.
GET /users/42
→ 200 OK
{ "id": 42, "name": "Ana Lopez", "email": "ana@example.com", "plan": "pro", "createdAt": "2025-03-14" }

GET /users/42/orders?limit=3
→ 200 OK
[ { "id": 981, "total": 120.00 }, { "id": 975, "total": 48.50 }, { "id": 960, "total": 15.00 } ]
The contract of a REST API is usually written in OpenAPI (formerly Swagger). OpenAPI 3.2.0, released on September 19, 2025, is the first minor version since 3.1.0 in 2021. It adds hierarchical tags, streaming media types such as Server-Sent Events, additionalOperations for extra HTTP methods like QUERY, and the OAuth 2.0 device flow. From one OpenAPI document you can generate documentation, client SDKs, mocks and contract tests.
REST is the default for public APIs — Stripe’s API is a well-known example — and for CRUD backends, admin panels, webhooks and much of the traffic between microservices. Our REST and OpenAPI technology page describes the tooling we use around it.
What is GraphQL?
GraphQL is a query language and runtime for APIs in which the client describes the exact shape of the data it needs, and the server returns that shape from a single endpoint. Facebook developed it in 2012 for its mobile apps, open-sourced it in 2015, and since 2018 it has been governed by the GraphQL Foundation under the Linux Foundation.
A GraphQL API starts with a schema written in the Schema Definition Language (SDL). The schema declares types, fields and the relationships between them, and it is the contract. Clients send three kinds of operations: queries to read, mutations to write and subscriptions to receive real-time updates. On the server, each field is backed by a resolver — a function that fetches that field from a database, another service or a REST API. Introspection lets tools ask the API for its own schema, which powers autocompletion, documentation explorers and type generation.
query {
  user(id: 42) {
    name
    orders(last: 3) { id total }
  }
}

→ 200 OK
{ "data": { "user": { "name": "Ana Lopez",
  "orders": [ { "id": 981, "total": 120.0 }, { "id": 975, "total": 48.5 }, { "id": 960, "total": 15.0 } ] } } }
One request returns the user and their last three orders, and only the fields the screen shows. The September 2025 edition of the GraphQL specification — the first new edition since October 2021 — added OneOf input objects (an input where exactly one field must be set), schema coordinates (a standard way to reference a type or field, such as User.email), descriptions on executable documents and full Unicode support.
Large platforms often offer both styles: GitHub provides a GraphQL API alongside its REST API. See our GraphQL technology page for the servers, gateways and client libraries we work with.
REST vs GraphQL: head-to-head comparison table
The table summarises how REST and GraphQL compare on the criteria that decide real projects. Each row is explained in the sections that follow.
| Criterion | REST | GraphQL |
|---|---|---|
| Endpoints | Many: one URL per resource or collection | Usually one (/graphql) |
| Who shapes the response | Server decides fields per endpoint | Client selects fields per request |
| Over- and under-fetching | Common without custom endpoints or field filters | Largely avoided by design |
| Contract | OpenAPI document (optional but standard) | SDL schema (mandatory, enforced at runtime) |
| Typing | Via JSON Schema in OpenAPI; not enforced by HTTP | Strongly typed; every query validated against the schema |
| Versioning | URL (/v1/) or header versions | Additive evolution plus @deprecated |
| Error handling | HTTP status codes and error bodies | errors array, often with HTTP 200 and partial data |
| HTTP and CDN caching | Native for GET with Cache-Control and ETag | Needs persisted queries over GET or client-side caches |
| Real-time | Webhooks, Server-Sent Events, WebSockets alongside | Subscriptions built into the spec |
| File uploads and downloads | Straightforward with multipart and binary responses | Not in the spec; usually handled by a separate REST endpoint or signed URLs |
| Security surface | Auth and rate limits per endpoint | Field-level auth, depth and cost limits, cost-based rate limiting |
| Tooling and learning curve | Universal HTTP tooling; low learning curve | Excellent typed tooling; steeper server-side learning curve |
| Best fit | Public, partner and service-to-service APIs; CRUD | Multi-client product APIs over nested, aggregated data |
Read the table as a list of trade-offs, not a scoreboard. REST is cheaper to run and easier to cache; GraphQL is more flexible for the teams that build user interfaces on top of it.
How do REST and GraphQL fetch data differently?
REST returns the data an endpoint was designed to return, while GraphQL returns the data a client asks for. That single difference explains most of the practical effects you will see.
With REST, a mobile profile screen might call GET /users/42 and receive twenty fields when it shows three — over-fetching. It might then need /users/42/orders and /orders/981/items to complete the screen — under-fetching, which turns into several sequential round-trips. On a fast office network that rarely matters. On a mobile connection with high latency, each extra round-trip adds visible delay. REST teams solve this with dedicated endpoints for heavy screens, query parameters such as ?fields= and ?include=, or compound documents. Those solutions work, but each new screen can mean a new backend change.
With GraphQL, the screen sends one query that names every field it needs across related objects, and gets back one response in exactly that shape. Frontend teams can build or change a screen without waiting for a new endpoint, as long as the data already exists in the schema.
The server side changes too. A REST endpoint has one route handler that loads everything it returns, often with a single optimised SQL query. A GraphQL request is executed field by field: each field’s resolver runs on its own, and the server combines their results.
The N+1 problem moves to the server
Field-by-field execution creates GraphQL’s best-known performance trap. A query for 50 orders, each with its customer, can trigger one database call for the orders plus 50 separate calls for customers — the N+1 problem. REST APIs suffer from N+1 too, but in REST it usually shows up as many HTTP calls from the client, where it is visible. In GraphQL it hides inside a single request.
The standard fix is batching: a DataLoader-style utility collects all customer IDs requested during one tick of execution and loads them in a single query, with a per-request cache. Every serious GraphQL server should use it from day one, and code review should check that new resolvers do not bypass it.
Which is faster, and which is easier to cache?
Neither REST nor GraphQL is faster as a rule, but REST is clearly easier to cache. Speed depends on what you measure: GraphQL often wins on round-trips and payload size for complex screens, while REST often wins on repeated reads that a CDN can serve without touching your servers.
REST and HTTP caching. A GET /products/123 response can carry Cache-Control: public, max-age=300 and an ETag. Browsers, reverse proxies and CDNs all understand those headers, as defined in RFC 9111. A product catalogue, a pricing page or public reference data can be served from the edge for most requests, and conditional requests with If-None-Match return a cheap 304 Not Modified when nothing has changed. This is the main reason read-heavy public APIs stay with REST.
GraphQL and caching. Most GraphQL clients send queries as POST requests to one URL, and CDNs do not cache POST bodies by default. Teams that need edge caching use three techniques:
- Persisted queries. Queries are registered at build time and referenced by a hash. The client sends
GET /graphql?id=<hash>&variables=…, so the URL becomes a cache key. Persisted queries also shrink request size and double as an allowlist for security. - Normalized client caches. Libraries such as Apollo Client, urql and Relay store objects by type and ID, so a user loaded on one screen is reused on the next without a network call.
- Server-side response or field caching, with cache hints per type or field, for data that is shared between users.
Payload and round-trips. For nested screens, GraphQL typically sends fewer requests and smaller payloads, which helps mobile users most. For simple resource reads, the difference is negligible, and a cache hit on a REST endpoint is hard to beat.
How do you version and evolve each API?
REST APIs usually version explicitly, while GraphQL APIs usually evolve one schema continuously. Both approaches work; both need discipline about breaking changes.
REST versioning. The most common pattern is a version in the URL (/v1/orders, /v2/orders); others use a header or a dated version string. Explicit versions are easy to understand and let you make breaking changes cleanly, which is why public APIs with many external consumers prefer them. The cost is maintenance: old versions must run, be tested and be secured until the last consumer migrates. Additive changes — new optional fields, new endpoints — do not need a new version at all.
GraphQL evolution. GraphQL encourages a single versionless schema. You add new fields and types freely, because existing queries only receive the fields they ask for. When a field must go, you mark it with @deprecated(reason: "Use fullName"); tools then warn client developers, and you remove it once usage reaches zero. The key enabler is field-usage telemetry: your gateway or server should record which clients request which fields, so you know when it is safe to remove one.
Both styles share the same rule: never rename or retype a field in place, never change its meaning silently, and run contract tests in CI — OpenAPI diffing for REST, schema checks for GraphQL — so that a breaking change fails the build instead of a client.
Error handling and security: what changes with GraphQL?
GraphQL changes both how errors are reported and where the security risks sit. Errors move from HTTP status codes into the response body, and the main new risk is that clients can write expensive queries.
Error handling
A REST API signals failure through status codes: 400 for bad input, 401 or 403 for auth problems, 404 for missing resources, 5xx for server faults. Monitoring, retries and alerting all build on that. A GraphQL server typically returns HTTP 200 even when something failed, with an errors array next to data. A single response can contain partial data — the user’s name but not their orders, because the orders service timed out. That is useful for resilient UIs, but it means your monitoring must parse response bodies, and your team needs a convention for error codes in the extensions field.
Security controls
In REST, each endpoint has a known cost, so authentication and rate limits per endpoint go a long way. In GraphQL, one endpoint accepts arbitrarily nested queries, so a public API needs additional controls:
- Depth and complexity limits that reject queries nesting too deeply or touching too many objects.
- Timeouts and pagination limits on every list field, so no query can request unbounded data.
- Persisted-query allowlists for first-party clients, so production accepts only queries your own apps shipped.
- Introspection policy: disabling introspection in production for private APIs reduces reconnaissance, though it is not a security boundary on its own.
- Field-level authorization in resolvers or a policy layer, because one query can reach data owned by many services.
- Rate limiting by query cost, not by request count, because one GraphQL request can do the work of fifty REST calls.
The OWASP API Security Top 10 — broken object-level authorization, unrestricted resource consumption and the rest — applies to both styles. GraphQL does not make an API less secure; it moves the controls from the edge into the schema and the resolvers.
When should you choose REST?
Choose REST when your API serves many unknown consumers, maps cleanly to resources, or needs to be cheap to cache and operate. These are the situations where we usually recommend it:
Public and partner APIs
External developers expect plain HTTP, OpenAPI docs, explicit versions and SDKs. REST meets those expectations with the least friction.
Resource-shaped CRUD and admin backends
When screens map closely to entities — customers, invoices, tickets — REST endpoints are simple to build, test and secure.
Read-mostly traffic with CDN caching
Catalogues, content and reference data benefit from Cache-Control, ETag and edge caching that work out of the box.
Webhooks and service-to-service calls
Event notifications, payment callbacks and simple internal calls fit the request–response model and every integration platform supports them.
Small teams and fast MVPs
A lean team shipping an MVP gets to production faster with REST and can add a GraphQL layer later if several clients appear.
When should you choose GraphQL?
Choose GraphQL when several clients need flexible access to connected data, and your team can invest in running it well. These are the situations where it usually pays off:
Web, iOS and Android on one backend
Each client fetches exactly what its screens need in one request — a strong fit for products that combine web and mobile app development.
Aggregating many backends
One graph over several microservices, legacy systems and third-party APIs gives clients a single, consistent model instead of a dozen endpoints.
Data-rich dashboards
Analytics views, CRMs and portals with deeply nested relationships avoid request waterfalls and custom aggregation endpoints.
Fast-moving product UI
Frontend teams iterate on screens without a backend release for every new field combination, as long as the data is already in the schema.
TypeScript and React teams
Generated types from the schema and mature clients for React give end-to-end type safety from database to component.
Can you use REST and GraphQL together?
Yes — and for many mid-size and large products, a hybrid is the most practical architecture. The usual rule is one API style per audience: GraphQL for your own client applications, REST for public, partner and webhook surfaces, and REST or gRPC between internal services.
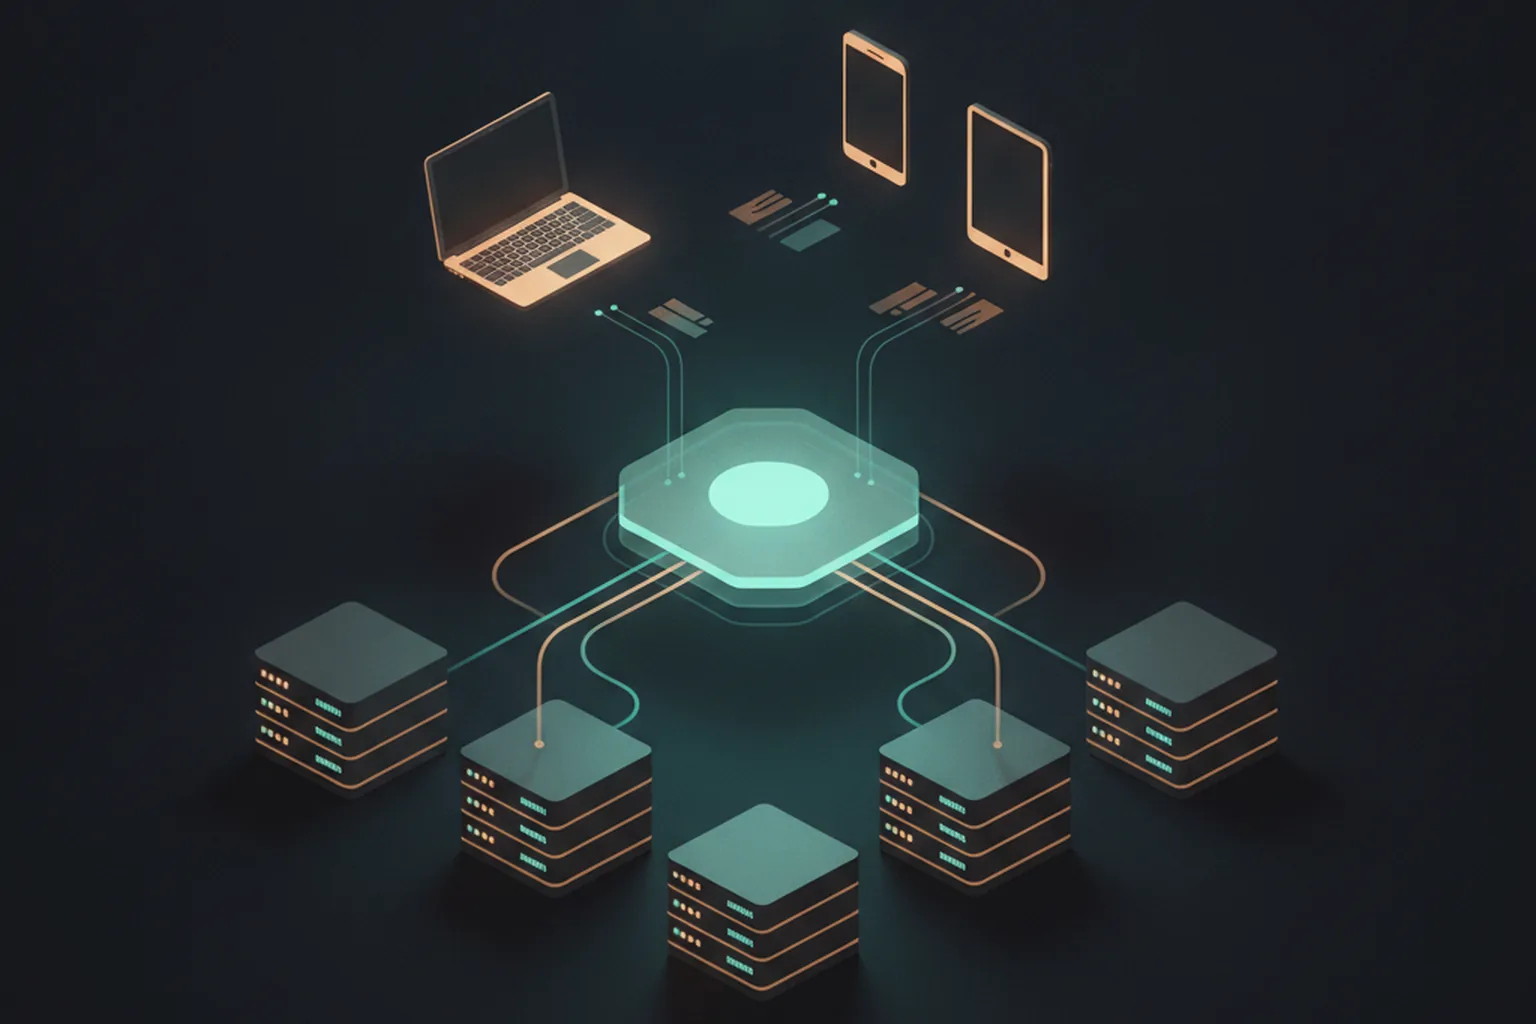
Three hybrid patterns come up most often:
- Backend for frontend (BFF). A thin GraphQL layer, owned by the client team, sits in front of existing REST services and shapes data for the web and mobile apps. The services stay unchanged.
- GraphQL gateway over REST and gRPC. A central gateway exposes one schema; resolvers call internal REST endpoints or gRPC services. This suits organisations with many backend services and a few client teams.
- Federation. Several teams each own a part of the schema (a subgraph), and a router composes them into one graph. It scales ownership across teams, but adds governance work: schema reviews, composition checks and shared conventions.
A hybrid is overkill when you have one client, one backend team and a mostly CRUD domain. In that case, a well-designed REST API with a few screen-specific endpoints will be cheaper to build and run.
How do you migrate between REST and GraphQL without a rewrite?
You migrate incrementally, by putting a GraphQL layer in front of the REST API you already have and moving clients screen by screen. A big-bang rewrite of the backend is rarely necessary and rarely a good idea.
A typical REST-to-GraphQL path looks like this:
- Wrap existing REST endpoints in resolvers. Start with a schema that mirrors the data your heaviest screens need, and implement resolvers that call the current REST API. Nothing in the backend changes yet.
- Design new screens schema-first. For new features, agree the SDL with client teams before writing resolvers. Use batching from the first resolver.
- Add persisted queries and limits before the first public release: depth and cost limits, timeouts and an allowlist for your own clients.
- Measure field and endpoint usage. Track which GraphQL fields each client uses and which REST endpoints still receive traffic.
- Retire unused REST endpoints only when telemetry shows they are idle — and keep the ones partners or webhooks depend on.
The reverse case is common too: a product built on GraphQL needs to give partners a simple, stable integration. The usual answer is a small REST facade with an OpenAPI contract, explicit versions and per-endpoint rate limits, implemented on top of the same domain services. Partners get what they expect, and your internal graph stays free to evolve.
The main risks are double maintenance during the transition, resolvers that reproduce the N+1 behaviour of the old client code on the server, and caching that silently disappears when reads move from GET endpoints to POST queries. Plan for all three in the migration estimate.
REST vs GraphQL for AI agents and LLM integrations
Both styles work for AI agents, but they help in different ways: REST through its widely supported OpenAPI contract, GraphQL through its typed, self-describing schema. Which matters more depends on how your agents are built.
OpenAPI documents are a common input for defining LLM tools: many agent frameworks and platforms can turn an operation — its path, parameters and description — into a function definition the model can call. Small, well-described REST operations map neatly to tools, and the new streaming media types in OpenAPI 3.2.0 give a standard way to describe Server-Sent Events responses that many AI products use.
GraphQL offers an agent a single discoverable surface: through introspection, an agent can read types, fields and descriptions and then compose exactly the query it needs. The September 2025 specification also allows descriptions on executable documents, so persisted queries and operations can carry human-readable explanations that tools — including LLM-based ones — can use as context.
The guardrails matter more than the style. An agent that writes arbitrary GraphQL queries needs the same cost limits, timeouts and field-level authorization as any public client, and often a curated set of persisted operations. An agent calling REST tools needs scoped credentials and rate limits. In both cases, expose a deliberately small, well-documented surface to the model rather than your whole API.
REST vs GraphQL: cost and timeline comparison
GraphQL usually costs more to set up and operate, and can save time later when several clients change quickly. The table below shows relative effort by work item. These are YuSMP planning heuristics for a senior team working from a scoped brief, not market statistics; your numbers depend on domain complexity and team experience. For overall project timelines, see how long it takes to build a web app in 2026.
| Work item | REST (YuSMP estimate) | GraphQL (YuSMP estimate) |
|---|---|---|
| Initial API design and contract | Baseline: OpenAPI per resource | Similar to slightly higher: schema design across domains, roughly +3–5 days |
| Authentication and authorization | Baseline: per-endpoint rules | Higher: field-level rules and policy layer, roughly +1–2 weeks |
| Caching layer | Low: HTTP headers and CDN configuration | Higher: persisted queries, client cache setup, roughly +1–2 weeks |
| Security hardening | Baseline: rate limits, input validation | Higher: depth and cost limits, cost-based rate limiting, roughly +1 week |
| Client integration per new screen | Often needs a backend change or new endpoint | Often frontend-only if data is already in the schema |
| Observability and monitoring | Low: per-endpoint metrics from standard tools | Higher: per-operation and per-resolver tracing, error parsing, roughly +1 week |
| Team ramp-up | Minimal for most backend engineers | Days to a few weeks for teams new to resolvers, batching and schema design |
| Long-term change cost | Grows with the number of clients and versions | Lower for multi-client products with frequent UI changes |
In short: for a single web client over a CRUD domain, REST is usually the cheaper path end to end. For a product with web and mobile clients that change every sprint, GraphQL’s higher upfront cost — typically a few extra engineering weeks in our planning — is often recovered through fewer backend changes per feature. A hybrid sits in between, and its cost depends mostly on how many services the gateway has to integrate. Your technology choices around it matter too; see our guide to choosing a web app tech stack in 2026.
Common mistakes when choosing between REST and GraphQL
Most API decisions that go wrong fail because of how they were made or operated, not because the style was wrong. These are the mistakes we see most often:
- Picking GraphQL for one simple client. A single web app over a CRUD domain gains little flexibility and pays the full operating cost.
- Exposing GraphQL publicly without cost limits. Without depth, complexity and pagination limits, one nested query can take down the backend.
- Ignoring N+1. Resolvers without batching look fine in development and collapse under production data volumes.
- Calling an RPC API “REST”. Endpoints like
POST /getUserOrderswith no caching headers lose most of REST’s advantages while keeping its limitations. - Versioning everything. Creating
/v2/for additive changes multiplies maintenance; evolve additively and reserve new versions for real breaking changes. - Deprecating without telemetry. Removing a REST endpoint or GraphQL field without usage data breaks the clients you forgot about, often old mobile app versions.
How YuSMP Group approaches API architecture
We don’t start with a preferred style. We start with the consumers: which clients will call the API, what shape of data each screen or integration needs, how much of the traffic is cacheable, and who will run the API in two years. The answer is written down as an architecture decision record before any endpoint is built.
From there we write the contract first — an OpenAPI document or a GraphQL SDL schema — and review it with the frontend, mobile and partner teams that will use it. We choose a hybrid only when there are several clients or several backend services to justify it, and we add load tests, contract tests and per-operation monitoring before launch. Our API development services cover this end to end; the GraphQL and REST and OpenAPI technology pages describe the stacks we use.
FAQ
Is GraphQL better than REST?
Neither is better in every case. GraphQL is better when several clients need differently shaped, nested data from many sources and your team can run schema governance and query-cost controls. REST is better for public and partner APIs, resource-shaped CRUD, heavy HTTP and CDN caching and teams that want simple operations. Many mature products use both.
Is GraphQL faster than REST?
Not as a rule. GraphQL can reduce round-trips and payload size for nested screens, which helps on mobile networks. REST can be faster for cacheable reads because GET responses are served from browser caches and CDNs without reaching your servers. Real speed depends on resolver design, database access, caching and network conditions, so measure your own critical screens.
Can GraphQL replace REST completely?
Technically yes, practically it rarely should. Webhooks, file downloads, health checks, OAuth flows and public partner APIs usually stay REST-style because the wider ecosystem expects plain HTTP. The common pattern is GraphQL for your own client applications and REST or gRPC for integrations, webhooks and service-to-service traffic.
Is REST outdated in 2026?
No. REST remains the default style for public APIs, and its contract format is still evolving: OpenAPI 3.2.0, released in September 2025, added hierarchical tags, streaming media types and support for additional HTTP methods. REST is simple, cache-friendly and understood by every HTTP tool, which keeps it relevant for most integrations.
Does GraphQL work with HTTP caching and CDNs?
Yes, but it takes deliberate work. Because most GraphQL requests are POSTs to one endpoint, CDNs cannot cache them by URL out of the box. Teams use persisted queries sent as GET requests with a query hash, so responses become cacheable by URL, and add normalized caches on the client such as Apollo Client, urql or Relay. Private, per-user data should not be cached at the edge with either style.
Is GraphQL secure for public APIs?
It can be, if you add the controls REST gets almost for free. A public GraphQL API needs query depth and complexity limits, timeouts, rate limiting based on query cost rather than request count, field-level authorization and often a persisted-query allowlist. Without them, one expensive nested query can overload your backend. The OWASP API Security Top 10 applies to both styles.
Should a mobile app use REST or GraphQL?
GraphQL is often a good fit when the same backend serves iOS, Android and web clients with different screens, because each client requests exactly the fields it needs in one round-trip. REST is a good fit when the app is simple, mostly reads cacheable resources or talks to a backend owned by another team. Old app versions stay in use for months, so plan for backward compatibility either way.
Can I use REST and GraphQL in the same project?
Yes, and it is common. A typical setup keeps REST or gRPC services internally and puts a GraphQL gateway or backend-for-frontend in front of them for web and mobile clients, while public, partner and webhook endpoints stay REST. GitHub, for example, offers both a REST API and a GraphQL API. Use one style per audience, not both for the same consumer.
What about gRPC?
gRPC is a third option, mainly for internal service-to-service communication. It uses HTTP/2 and a compact binary format defined with Protocol Buffers, which suits high-volume, low-latency calls between microservices. It is less convenient for browsers and public consumers, so it usually complements REST or GraphQL rather than replacing them at the edge.
Verdict: REST or GraphQL for your project?
In 2026, the REST vs GraphQL decision is not about which style is more modern — both are mature, actively specified and running at scale. It is about who consumes your API and how much operating complexity your team is ready to own.
- Choose REST if your API serves public or partner developers, your domain is resource-shaped, your traffic is read-heavy and cacheable, or your team is small and needs to ship quickly.
- Choose GraphQL if several clients need different views of connected data, frontend teams change screens every sprint, and you can invest in batching, cost limits, persisted queries and per-resolver monitoring.
- Choose a hybrid if you have both: GraphQL or a BFF for your own apps, REST for partners and webhooks, and REST or gRPC between internal services.
A one-line decision rule: start with REST unless you can name at least two clients whose data needs differ — then evaluate GraphQL, and price in its operating cost before you commit.