
The short answer
Microsoft plans to run most of its own AI inference on in-house silicon, starting with the Maia 300 accelerator in 2027. On October 12, 2026, it said the Maia family will scale to multi-gigawatt deployments and become the primary inference system for its products, with a claimed 40% more tokens per megawatt than leading GPU systems.
For companies that buy AI, ML and data engineering on Azure, this is less a hardware story than a pricing and capacity story. Inference, not training, is where most enterprise AI budgets now go, and the hardware behind Copilot and Microsoft Foundry endpoints is about to change underneath the applications that call them.
What did Microsoft announce?
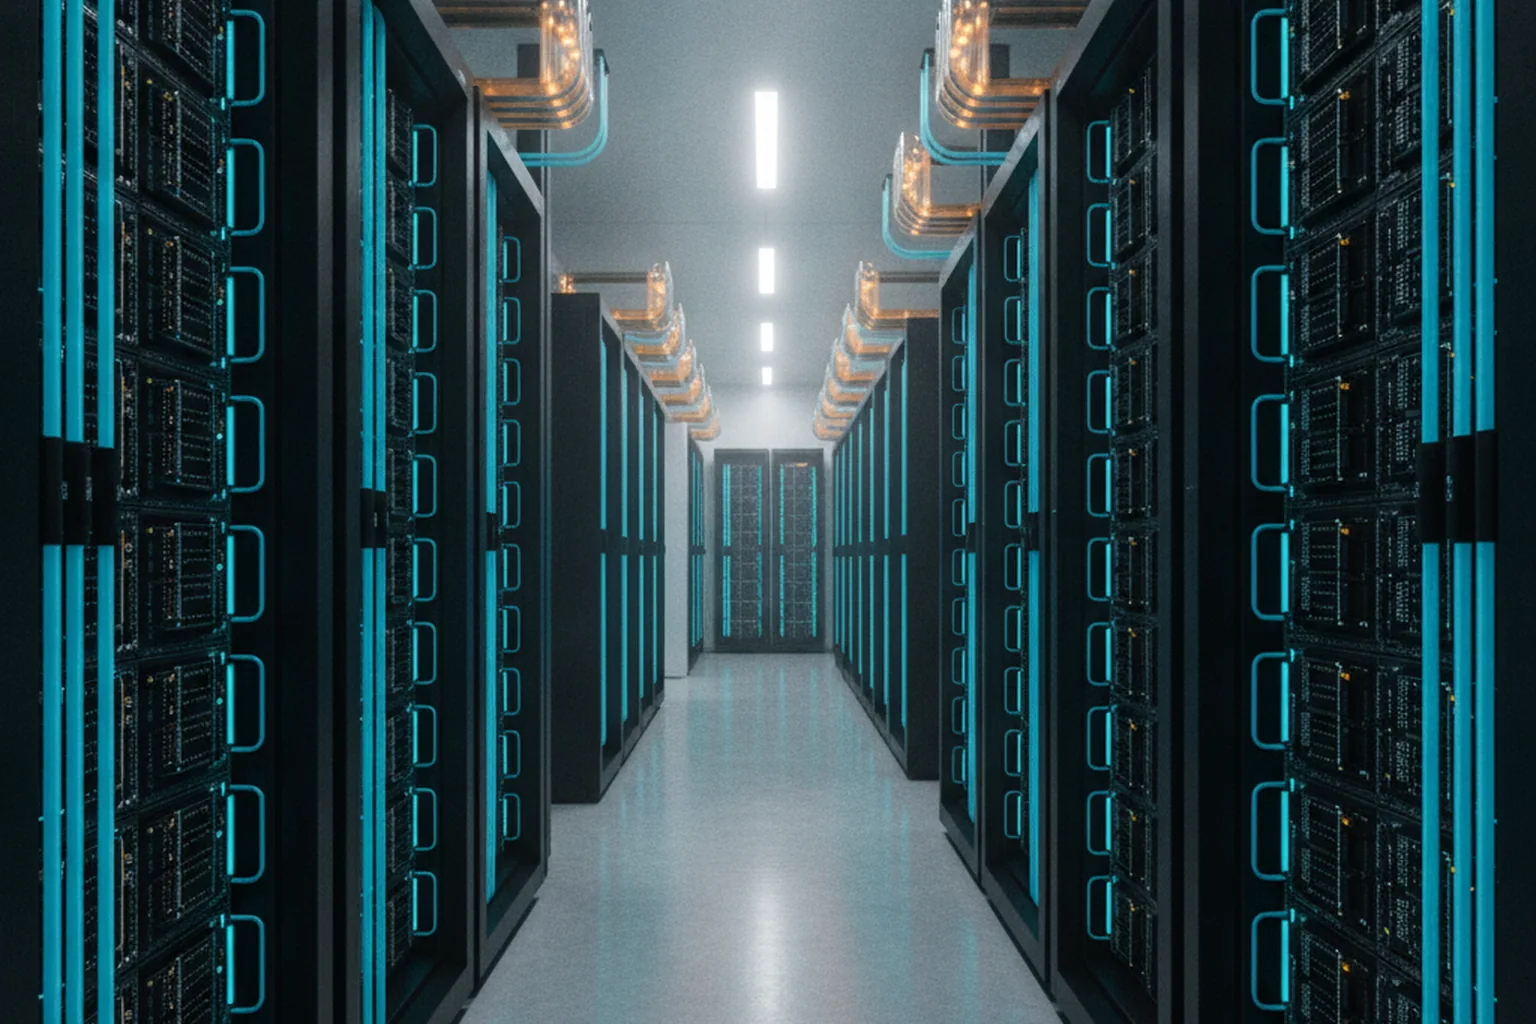
Maia 300 is the third generation of Microsoft’s custom accelerator program, which began with the first Maia chip in 2023 and continued with Maia 200, unveiled in January 2026. Microsoft describes the new part as a complete system rather than a chip: accelerators, an Ethernet-based AI network that links up to 96 chips in a rack and up to 12,288 in a superpod, and liquid cooling that removes more than 80% of a rack’s heat.
The design targets the workloads that dominate production AI today: long-context reasoning, latency-sensitive chat and multi-step agent tasks. It supports low-precision formats, including an enhanced MXFP4 and sub-3-bit storage, which cut memory traffic when models generate tokens. CNBC reports that Microsoft will mainly rely on its own silicon to handle incoming AI requests, and Bloomberg reports the chips will be installed in its data centers next year.
Maia 200 is already in production in the United States, Europe and Australia. Microsoft says it delivers up to 1.7x more tokens per watt for Teams, Copilot and Cowork experiences. All performance figures here are Microsoft’s own; independent benchmarks are not yet available.
Why is Microsoft building its own inference chips?
Training a frontier model is a one-off cost, while serving it is a bill that grows with every user and every agent step. Agent workloads make this worse: one task can trigger dozens of model calls over long contexts. That makes tokens per watt, and the power available in each data center, the main limit on how much AI a cloud can sell.
Owning the accelerator lets Microsoft tune silicon, network and cooling for its own model traffic and rely less on Nvidia’s supply and pricing. It follows the path Google took with TPUs and Amazon with Trainium and Inferentia. The difference is scale of intent: Microsoft now says Maia, not GPUs, will be the default inference engine for its own products.
What it means for US & EU software teams
First, expect inference economics to shift, not just prices. If Maia delivers what Microsoft claims, Azure gains cheaper inference capacity for its own services. That may show up as lower prices or higher rate limits on Azure OpenAI and Foundry endpoints, but nothing has been announced. Budget on current pricing and treat any drop as upside.
Second, the serving stack under your model will change without notice. Low-precision formats and new kernels can make outputs differ slightly from the same model on GPUs. For regulated FinTech or HealthTech flows, that means keeping a fixed evaluation set and re-running it on a schedule, not just when you change the prompt or model version.
Third, portability is your leverage. Every hyperscaler now has its own silicon. Teams that call models through a thin gateway, with prompts and evaluations stored as code, can move workloads between Azure, AWS and Google Cloud as capacity and pricing shift. Teams that hard-code one provider’s SDK across the codebase will pay for each move. For EU deployments, also confirm which regions get Maia-backed capacity, as data residency commitments still apply to wherever inference runs.
What should teams do before 2027?
- Measure cost per task. Track what one support reply, document review or agent run costs end to end, not only the per-token list price.
- Put a gateway in front of model calls. Route requests through one internal layer so you can switch model, provider or region by configuration.
- Freeze an evaluation set. Keep a versioned set of real prompts with expected answers and run it weekly against production endpoints to catch silent quality drift.
- Ask about capacity and regions. Use your next Microsoft renewal to ask which services and regions move to Maia-backed capacity and whether committed-spend terms change.
- Keep training and inference plans separate. Fine-tuning will likely stay on GPUs; serving may not. Plan budgets and vendor choices for each on their own terms.
Frequently asked questions
What is Microsoft Maia 300?
Maia 300 is the third generation of Microsoft’s in-house AI accelerator, announced on October 12, 2026. It is built for inference rather than training: running trained models for long-context reasoning, chat and multi-step agent tasks. Production deployments start in 2027.
When will Maia 300 be available?
Microsoft says Maia 300 production deployments begin in 2027 and that the Maia family will scale to multi-gigawatt deployments from then on. Its predecessor, Maia 200, is already in production in the United States, Europe and Australia.
Can Azure customers rent Maia 300 directly?
Microsoft has not announced Maia virtual machines. The announcement describes Maia as the system behind Microsoft services such as Copilot, GitHub Copilot and Microsoft Foundry, so most customers will reach it indirectly through model endpoints rather than as raw hardware.
Does Maia replace Nvidia GPUs at Microsoft?
Not entirely. Microsoft says Maia will become the primary inference system for its own products and services, while GPU-based systems remain part of its fleet. Training and many customer workloads are expected to keep running on Nvidia and AMD hardware.
What should teams building on Azure do now?
Keep model calls behind an abstraction layer, track cost per task rather than per token, run evaluation suites whenever a provider changes the serving stack, and ask your Microsoft account team which regions and services will move to Maia-backed capacity in 2027.
Sources
Official Microsoft Blog — Microsoft to expand Azure Maia system to multi-gigawatt deployments
Azure Blog — Deep dive into Azure Maia 300 architecture
CNBC — Microsoft will mainly use its Maia chips for AI inference
Bloomberg — Microsoft to install Maia 300 chips in data centers for AI software next year
GeekWire — Microsoft makes ‘biggest bet yet’ on its own silicon